Conference
CORE A26.5% acc.
❝ 1 citations
K-MaT: Knowledge-Anchored Manifold Transport for Cross-Modal Prompt Learning in Medical Imaging
Medical Image Computing and Computer Assisted Intervention – MICCAI 2026, Lecture Notes in Computer Science, September 2026
Abstract
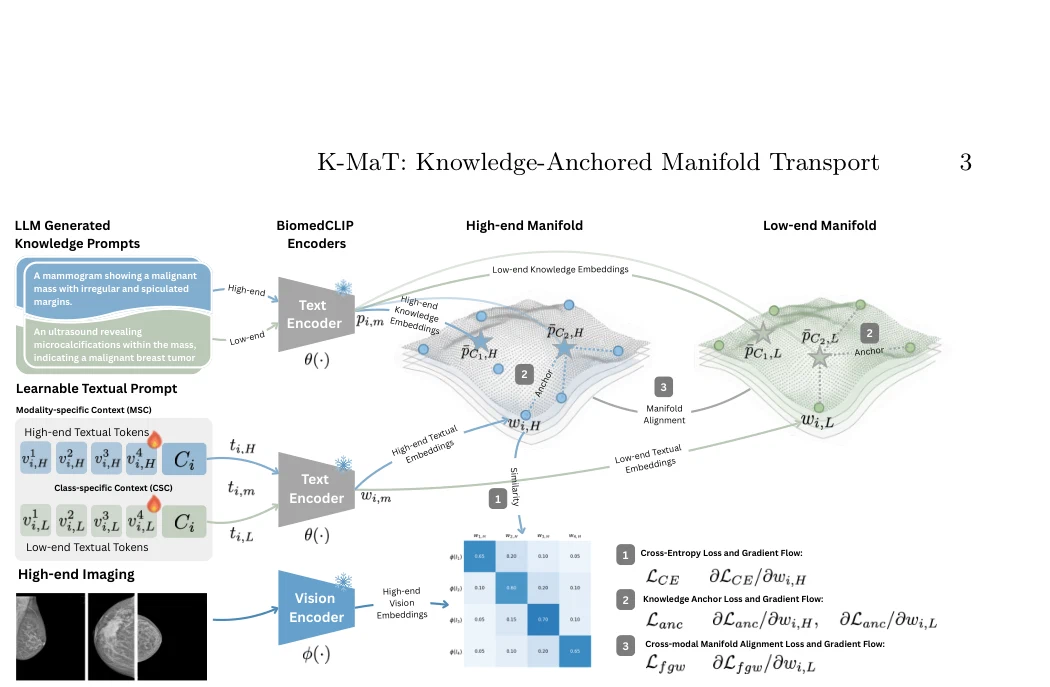
Large-scale biomedical vision-language models (VLMs) adapted on high-end imaging (e.g., CT) often fail to transfer to frontline low-end modalities (e.g., radiography), collapsing into modality-specific shortcuts. We propose K-MaT (Knowledge-Anchored Manifold Transport), a prompt-learning framework that transfers decision structures to low-end modalities without requiring low-end training images. K-MaT factorizes prompts, anchors them to clinical text descriptions, and aligns the low-end prompt manifold to the visually-grounded high-end space using Fused Gromov-Wasserstein optimal transport. We evaluate K-MaT on four cross-modal benchmarks, including dermoscopy, mammography to ultrasound, and CT to chest X-ray. K-MaT achieves state-of-the-art results, improving the average harmonic mean of accuracy to 44.1% (from BiomedCoOp’s 42.0%) and macro-F1 to 36.2%. Notably, on the challenging …
Interactive explainer
Auto-generated. This explainer was generated automatically with Claude (Anthropic) from the published paper. It simplifies the method and may contain errors — for a correct understanding, and for all results and numbers, please refer to the published paper (publisher version).
Research themes
Research areas
Funded by
Lab authors


Cite (BibTeX)
@article{zeng2026k,
 author = {Zeng, Jiajun and Albarqouni, Shadi},
 journal = {arXiv preprint arXiv:2603.06340},
 title = {K-MaT: Knowledge-Anchored Manifold Transport for Cross-Modal Prompt Learning in Medical Imaging},
 year = {2026}
}